Portfolio · AI engineer (RAG)Yodhimas Geffananda
Telusur.
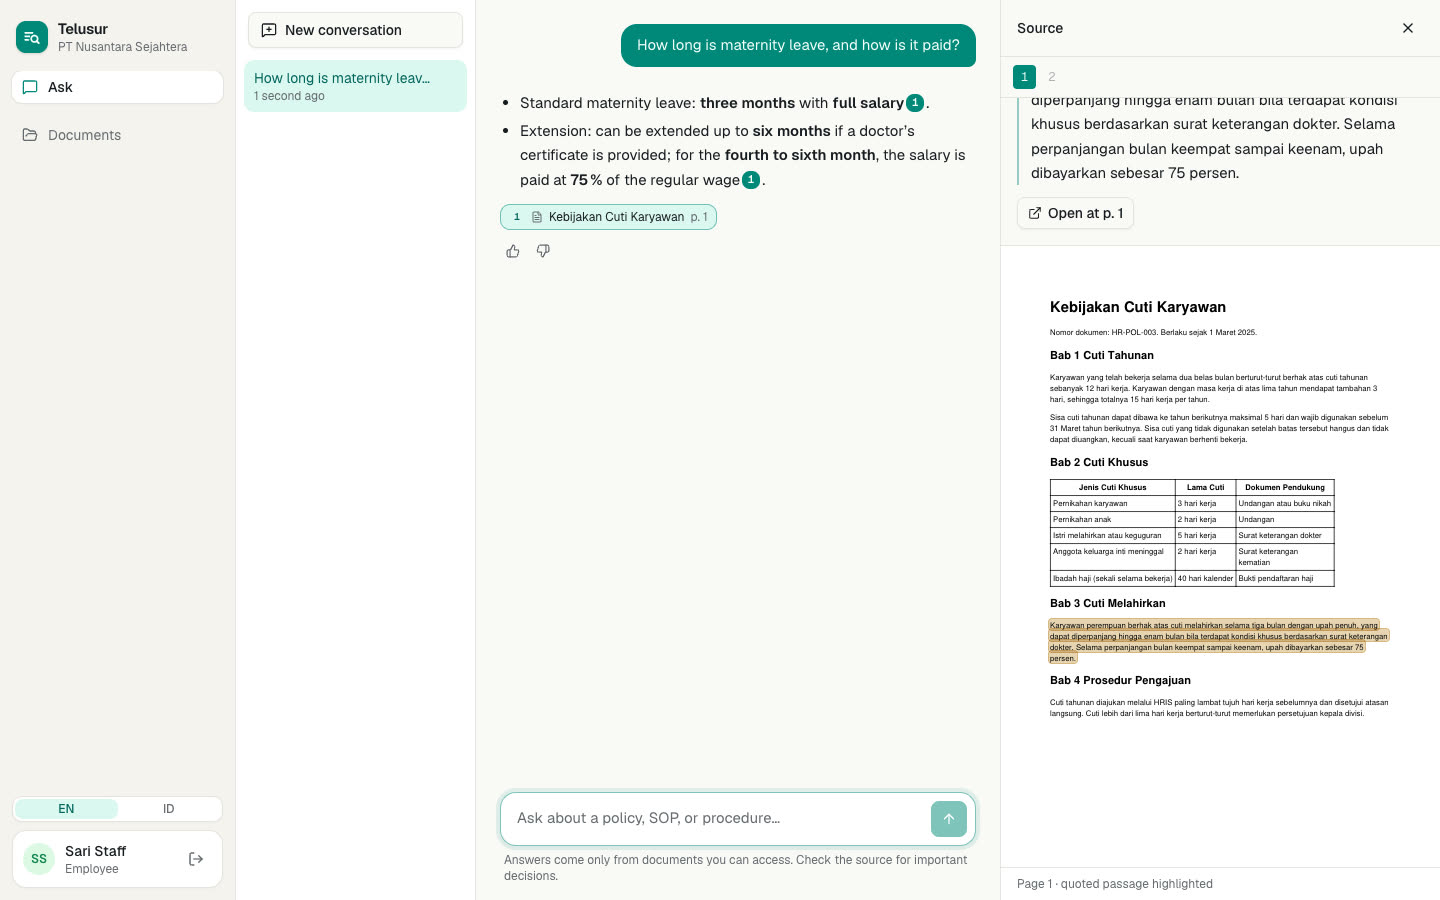
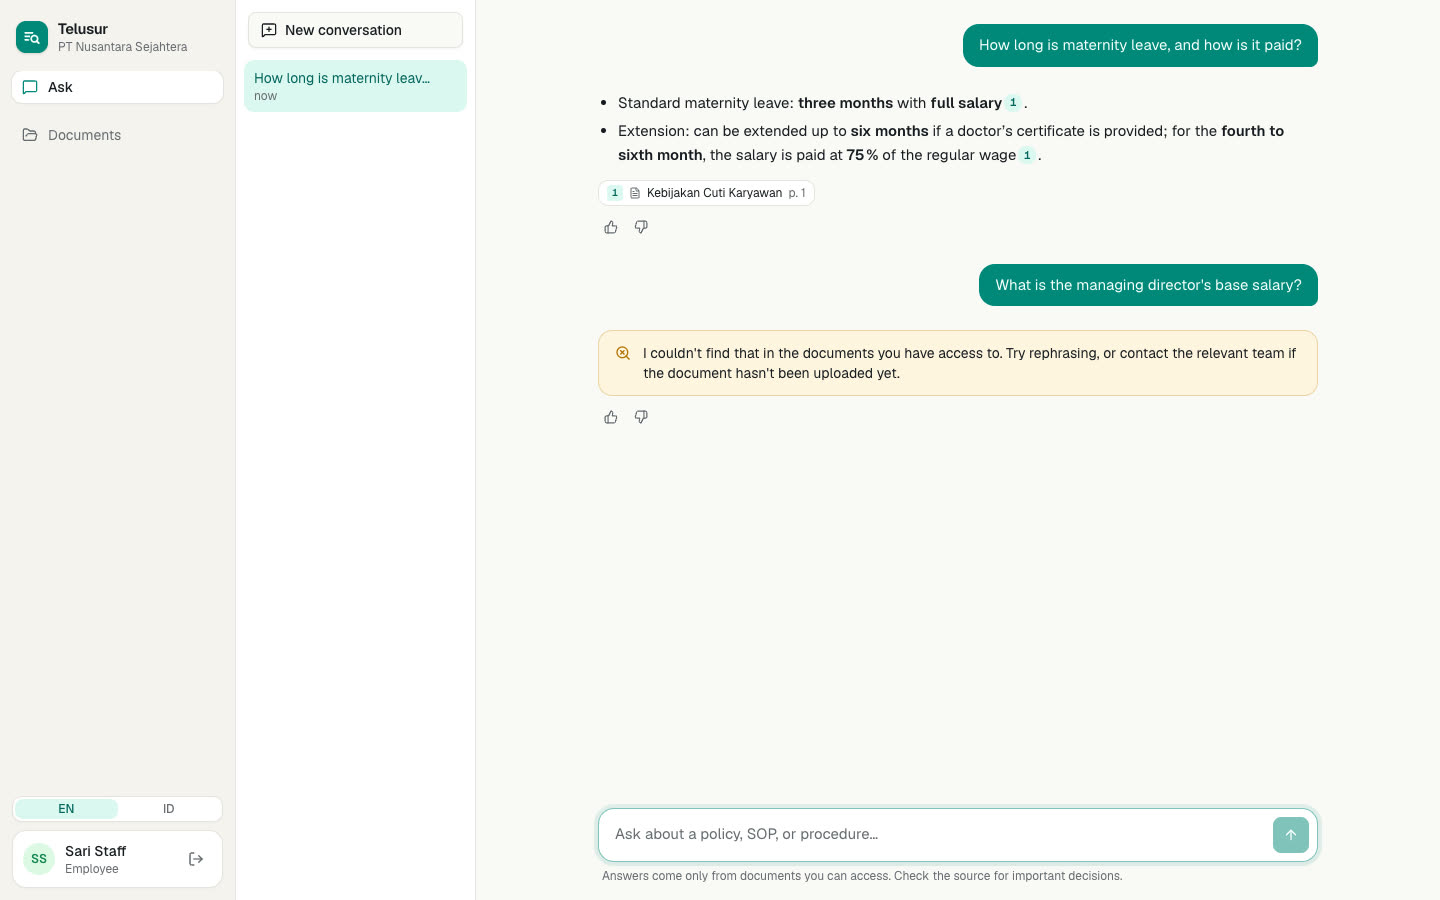
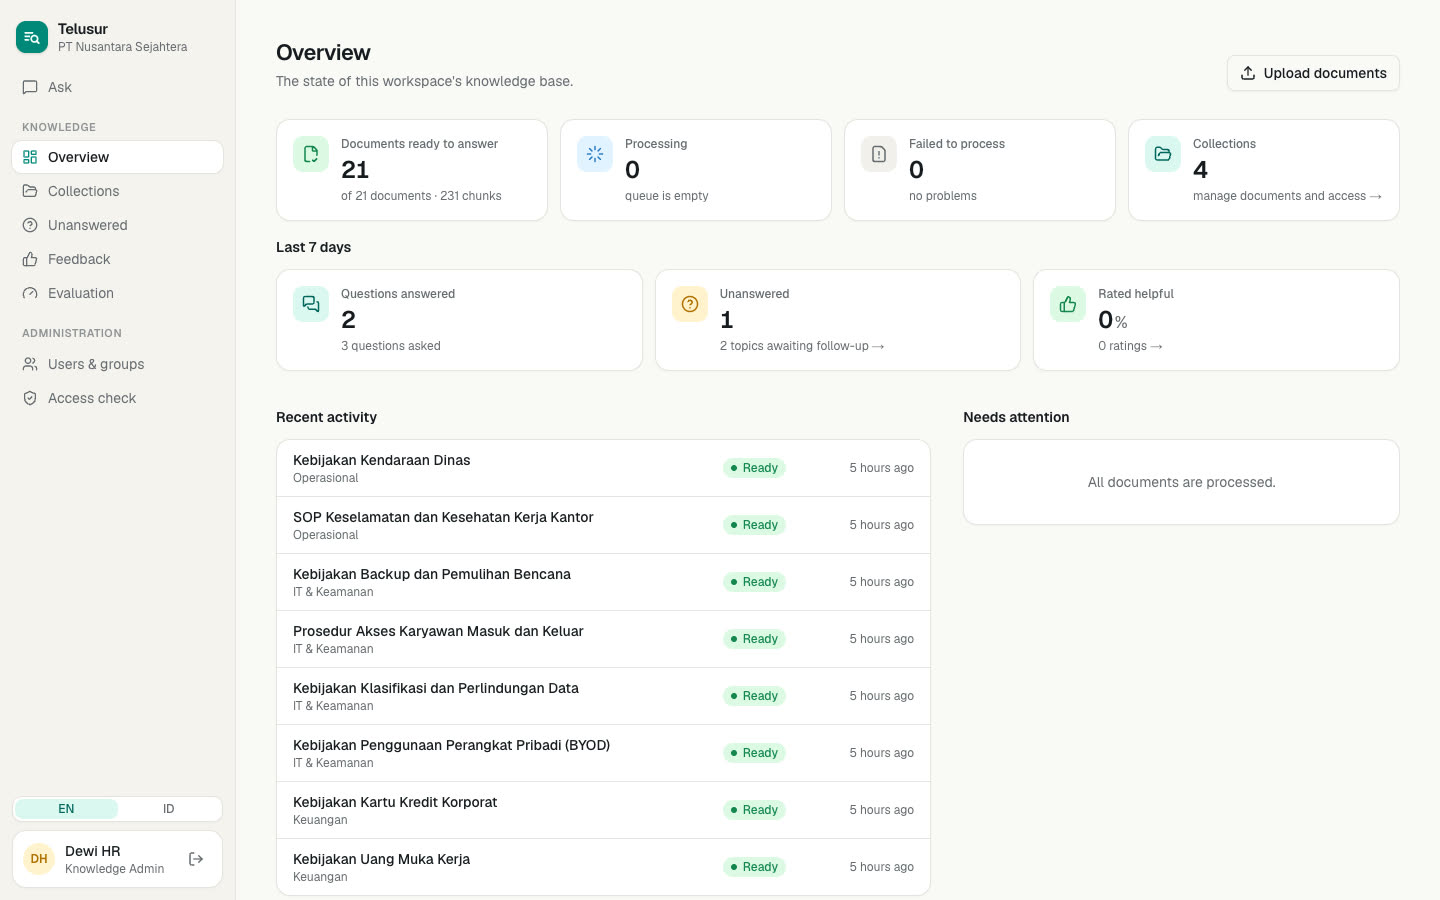
An internal knowledge assistant (English and Indonesian interface) for mid-size and large companies. Employees ask in plain language and get answers from company documents, with the page cited, drawn only from documents they are allowed to read. Admins get versioning, an append-only audit log, unanswered-question topics, and a measured evaluation of answer quality.
2:54 · no sound · English interface with captions · recorded locally on the fictional PT Nusantara Sejahtera policy set (documents in Indonesian).
Chapters
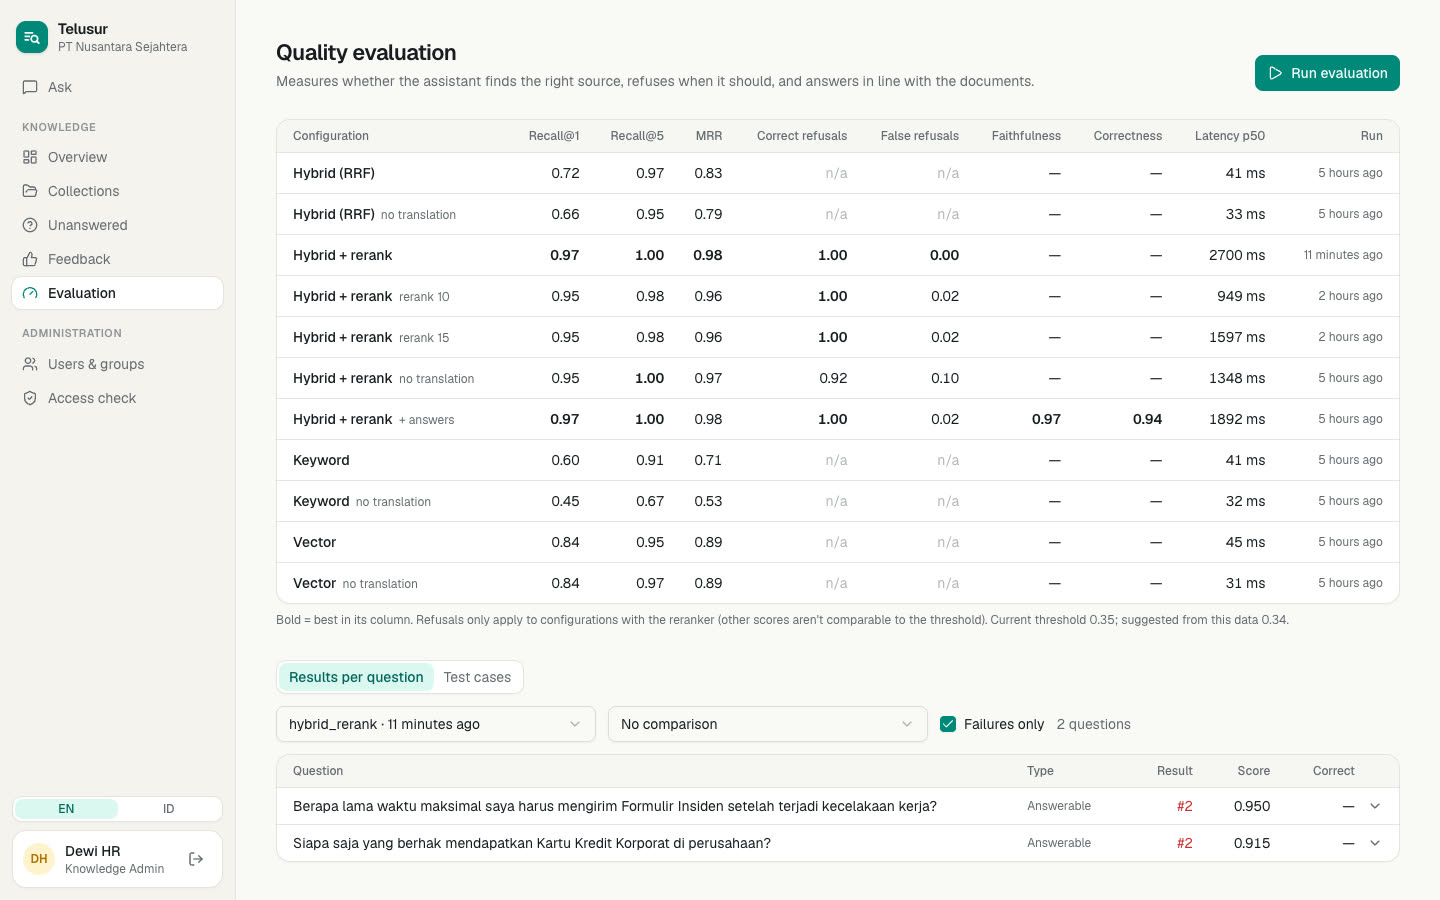
Measured, not claimed — 22 policy documents, 71 test questions (~30% English)
| Retrieval method | Recall@1 | Recall@5 | MRR | Correct refusals | False refusals |
|---|---|---|---|---|---|
| Keyword only | 0.60 | 0.91 | 0.71 | — | — |
| Vector only (bge-m3) | 0.84 | 0.95 | 0.89 | — | — |
| Hybrid (vector + keyword, RRF) | 0.72 | 0.97 | 0.83 | — | — |
| Hybrid + rerank, no query translation | 0.95 | 1.00 | 0.97 | 92% | 10% |
| Hybrid + rerank, one translation | 0.97 | 1.00 | 0.98 | 100% | 2% |
| Hybrid + rerank, three paraphrases (production) | 0.97 | 1.00 | 0.98 | 100% | 0% |
0.97Faithfulness (LLM judge)
0.94Answer correctness
93%Answers with citations
0 / 3Restricted documents leaked
- The reranker is the component that matters. It lifts Recall@1 from 0.84 to 0.97 and is the only score calibrated enough to decide "I don't know".
- Hybrid without reranking was worse than vector alone. Keyword search pulls loosely related passages up; it pays off only as a candidate source for the reranker.
- Every false refusal was an English question whose right passage was already ranked first; cross-lingual reranker scores were too low. Translating the query cut false refusals from 10% to 2%; searching with three Indonesian paraphrases took them to 0%, because one translation can pick words the documents don't use (“maternity leave” → “cuti hamil” instead of “cuti melahirkan”).
Under load — concurrent users on one laptop GPU, LLM stubbed to measure this system
| Rerank candidates | Recall@1 | Peak chats / min | p95 first token, 20 users | Errors, 20 users |
|---|---|---|---|---|
| 20 (default, quality first) | 0.97 | 42 | 37 s | 0% |
| 10 (high-traffic setting) | 0.95 | 65 | 21 s | 0% |
- The load test found two concurrency bugs before any user did: the embedder and reranker shared the GPU without a common lock (the process aborted at 5 users), and requests held a database connection while queued for the GPU (the pool ran dry at 20). Both fixed; 0% errors at 20 users.
- The reranker is also the throughput ceiling. Halving its candidates buys 54% more throughput for one question in 58 lost at rank 1 — a measured trade-off, exposed as a setting instead of a silent default.
What it shows
Retrieval & answers
- Structure-aware chunking with page numbers
- Vector + full-text, RRF, cross-encoder rerank
- Streaming answers, verified citations, refusal threshold
Enterprise controls
- Multi-tenant with Postgres row-level security
- Per-collection and per-document access, enforced in SQL
- Append-only, partitioned audit log
Quality loop
- Generated test set + manual verification
- LLM judge on a separate model
- Thumbs-down feedback becomes a regression test
Screens